Fisher Divergence
Chapter 17: Score Function and Energy-Based Models — Fisher Divergence Score Matching
From the book
Chapter 17: Score Function and Energy-Based Models. In the chapter mind map this icon labels Fisher Divergence Score Matching. The discussion below is excerpted and lightly edited from § Fisher Divergence Score Matching in Mathematics for AI and Machine Learning.
This is the Fisher divergence between $p_{\text{data}}$ and the model: it compares two distributions through their scores, weighted by the data distribution, and it vanishes exactly when the scores agree everywhere the data lives. (It shares the score with the Fisher information of Section the referenced section: for a location parameter, $\mathbb{E}_p[\nabla_{\mathbf{x}}\log p\,\nabla_{\mathbf{x}}\log p^\top]$ is the Fisher information matrix.) It is related to the KL divergence (Chapter the referenced section, Section the referenced section) by de Bruijn's identity: if both distributions are blurred by the same Gaussian noise, $p_t = p \mathcal{N}(\mathbf{0}, tI)$ and $q_t = q \mathcal{N}(\mathbf{0}, tI)$, then $\frac{d}{dt} D_{\mathrm{KL}}(p_t \,\|\, q_t) = -\frac{1}{2}\,\mathbb{E}_{p_t}\left[\|\nabla \log p_t - \nabla \log q_t\|_2^2\right]$. Adding noise always shrinks the KL divergence, at a rate equal to half the Fisher divergence; integrating over the noise level turns the Fisher divergences at all noise scales into a KL divergence, which is why multi-scale score matching also controls the likelihood (see the Fokker-Planck view in Chapter the referenced section).
where $s_{\theta,i}(\mathbf{x})$ is the $i$-th component of $\mathbf{s}_\theta(\mathbf{x})$.
Using integration by parts[^integration-by-parts] transforms the objective, but introduces a boundary term. To eliminate this term, we assume $p_{\text{data}}(\mathbf{x}) \to 0$ as $\|\mathbf{x}\| \to \infty$. Here's why this assumption works:
What this drawing shows
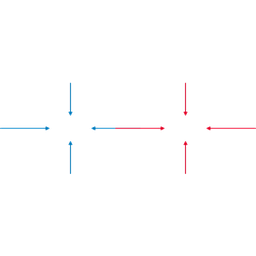
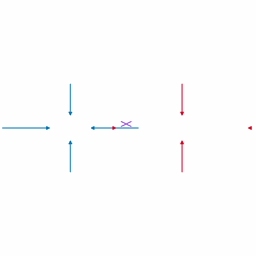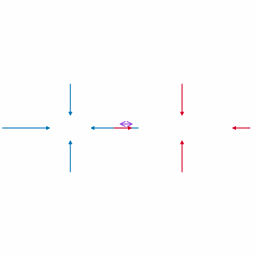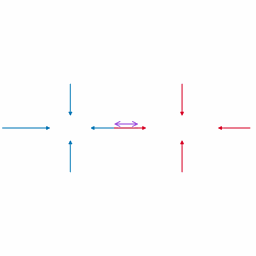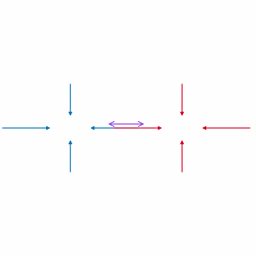
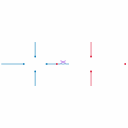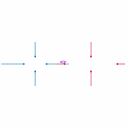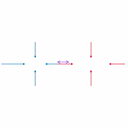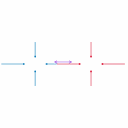
What you see. True score field $s$ (blue) fixed; red $s_\theta$ arrows shrink inward and the purple gap closes as the Fisher objective is minimized.
In the mind map. Chapter 17 — Fisher Divergence Score Matching. See From the book above for definitions, figures, and worked examples.
Where to read next
Read the full definitions, figures, and worked examples in Chapter 17: Score Function and Energy-Based Models — see the mind-map node Fisher Divergence Score Matching.