Nyström
From the book
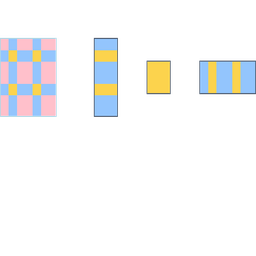
Chapter 9: Matrix Decompositions and Beyond. In the chapter mind map this icon labels Nyström: $K \approx C W^{+} C^\top$. The discussion below is excerpted and lightly edited from § Nyström Approximation in Mathematics for AI and Machine Learning.
For a symmetric positive semi-definite $K \in \mathbb{R}^{N \times N}$, such as a kernel matrix $K_{mn} = \kappa(\mathbf x^{(m)}, \mathbf x^{(n)})$ (the matrix chapter), the CUR decomposition can use the same index set $\mathcal{J}$ of size $k$ for rows and columns. With $C = K(:, \mathcal{J}) \in \mathbb{R}^{N \times k}$ and $W = K(\mathcal{J}, \mathcal{J}) \in \mathbb{R}^{k \times k}$, @eq:cur-decomposition becomes the Nyström approximation
where $W^{+}$ is the pseudoinverse (the matrix chapter), equal to $W^{-1}$ when $W$ is invertible. It is exact when $\mathrm{rank}(W) = \mathrm{rank}(K)$. Otherwise the error $K - CW^{+}C^\top$ is zero on the rows and columns $\mathcal{J}$ and equals the Schur complement of $W$ (the matrix chapter) elsewhere, which is positive semi-definite, so the approximation never overestimates: $\mathbf x^\top C W^{+} C^\top \mathbf x \le \mathbf x^\top K \mathbf x$. It needs only the $Nk$ entries of $C$, never all $N^2$ entries of $K$.
For example, the Gram matrix $K = XX^\top$ of the four points $(1,0), (0,1), (1,1), (2,1)$ has rank 2. With $\mathcal{J} = \{0, 1\}$, $W = I$ and $C = X$, so $CW^{-1}C^\top = XX^\top = K$ exactly, from 8 of its 16 entries.
What this drawing shows
What you see. Nyström: a symmetric matrix approximated from a few landmark columns, `K ≈ C W⁺ Cᵀ`.
In the mind map. Chapter 9 — Nyström. See From the book above for definitions, figures, and worked examples.
Where to read next
Read the full definitions, figures, and worked examples in Chapter 9: Matrix Decompositions and Beyond — see the mind-map node Nyström.