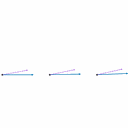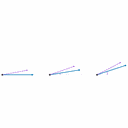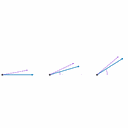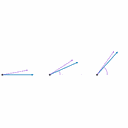
Rotary Position Embedding (RoPE)
From the book
Chapter 3: Subspaces and Orthogonality. In the chapter mind map this icon labels RoPE. The discussion below is excerpted and lightly edited from § Rotary Position Embedding (RoPE) in Transformers in Mathematics for AI and Machine Learning. Related material also appears in Chapter 6 (RoPE & Augmentation).
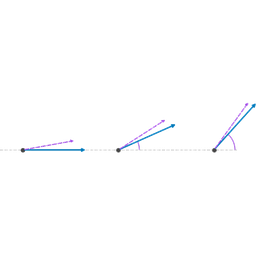
Rotary Position Embedding (ROPE)[^rope] encodes positional information in Transformers using complex number rotations. For a query vector $\mathbf{q}_m \in \mathbb{R}^{d}$ at position $m$ and a key vector $\mathbf{k}_n \in \mathbb{R}^{d}$ at position $n$, ROPE splits each $d$-dimensional vector into $d/2$ pairs: $(\mathbf{q}_m^{(0)}, \mathbf{q}_m^{(1)}), (\mathbf{q}_m^{(2)}, \mathbf{q}_m^{(3)}), \ldots, (\mathbf{q}_m^{(d-2)}, \mathbf{q}_m^{(d-1)})$. Each pair $(q_m^{(2i)}, q_m^{(2i+1)})$ is treated as a complex number $q_m^{(2i)} + i \cdot q_m^{(2i+1)}$ and rotated by angle $m \theta_i$:
where $\theta_i = 10000^{-2i/d}$ is the base frequency for dimension pair $i$. The same rotation is applied to the corresponding key vector pairs with angle $n \theta_i$.
The rotation matrix $\begin{pmatrix} \cos\theta & -\sin\theta \\ \sin\theta & \cos\theta \end{pmatrix}$ corresponds to multiplication by $e^{i\theta} = \cos\theta + i\sin\theta$ in the complex plane, connecting to the eigenvalues of orthonormal matrices: rotations have eigenvalues $e^{\pm i\theta}$ with $|e^{\pm i\theta}| = 1$. When computing the attention score, the rotation angles combine so that the result depends only on the relative position $n-m$. Write $R(\alpha)$ for the rotation by angle $\alpha$. Rotations compose by adding angles, $R(\alpha)R(\beta) = R(\alpha+\beta)$, and a rotation is orthonormal with inverse $R(\alpha)^\top = R(\alpha)^{-1} = R(-\alpha)$. Hence, for each dimension pair,
Each vector is rotated by its own absolute position, yet the score sees only the difference $n-m$. This relative position encoding emerges naturally from the geometric properties of rotations, enabling the model to capture positional relationships without explicit position embeddings.
ROPE's reliance on complex rotations provides theoretical grounding: the rotation preserves vector norms (since $|e^{i\theta}| = 1$), so positions change the direction of $\mathbf q$ and $\mathbf k$ but not their length. Note that relative encoding alone does not make a model work on sequences much longer than those seen in training: at unseen positions the low-frequency pairs reach rotation angles never encountered, which is why long-context models rescale the angles (position interpolation, NTK-aware scaling, YaRN).
[^rope]: Su et al., [RoFormer: Enhanced Transformer with Rotary Position Embedding](https://arxiv.org/abs/2104.09864), 2021. \url{https://arxiv.org/abs/2104.09864}
What this drawing shows
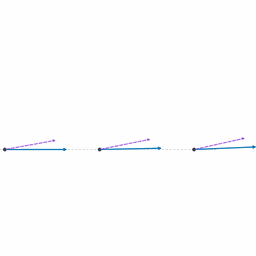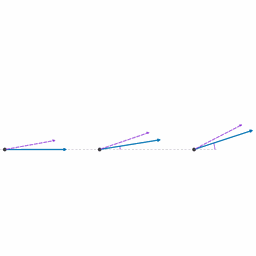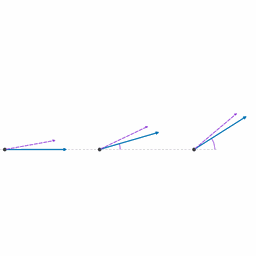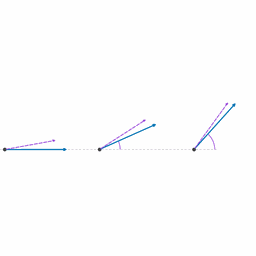
What you see. Token positions fixed; blue $q$ and purple $k$ rotate by $m\theta$ as position $m$ increases along the sequence.
In the mind map. Chapter 3 — RoPE. See From the book above for definitions, figures, and worked examples.
Also appears in Ch. 6 (RoPE & Augmentation).
Where to read next
Read the full definitions, figures, and worked examples in Chapter 3: Subspaces and Orthogonality — see the mind-map node RoPE.
This concept is also referenced in Chapter 6 (RoPE & Augmentation).